nice came up while I was preparing for an SRE interview, and I gave the answer I would have given anyone who asked: it sets a process’s priority, from -20 to 19, lower number wins, and that priority is also what decides which processes get thrown out when the node runs low on memory. The first half is right. The second half is a different subsystem entirely, and once I started pulling on that thread I found a few more things in top whose meaning I had never actually checked. This post is those pointers, each kept short.
nice is a CPU knob, and only a CPU knob
The range is -20 to 19, and sched(7) is specific about what it covers: the nice value affects the scheduling of SCHED_OTHER and SCHED_BATCH processes, which is to say ordinary tasks under the fair scheduler. Real-time classes ignore it. Lower is more favourable. nice -n 10 ./job adds 10 to the niceness the shell hands it, so 10 from an ordinary shell at 0; renice -n 5 -p 4211 changes one that is already running; and the NI column in ps -l or top shows the current value.
Going down is the privileged direction. Anyone can make their own process nicer; making it less nice needs either CAP_SYS_NICE or a permissive RLIMIT_NICE. getrlimit(2) gives the rule: the limit is a ceiling on how far the nice value can be raised in priority, calculated as 20 - rlim_cur, so the useful range runs from 1 (allowing nice 19) to 40 (allowing nice -20). ulimit -e shows yours, and for an ordinary user it is almost always 0, which by that formula is a ceiling of nice 20, outside the range entirely, so no negative nice at all. It is also a limit in the ulimit sense: it belongs to one process, children inherit it across fork, and no cgroup file knows it exists. cpu.max in the next section is the other kind, one file that governs every task in the group at once.
None of that touches memory. When a machine runs short, the order of events is reclaim first, dropping page cache and swapping out if there is swap, and the OOM killer last, and the OOM killer does not read NI. It reads /proc/<pid>/oom_score, which proc(5) describes as a score based on the amount of memory the process uses, where a higher score makes the process more likely to be selected. /proc/<pid>/oom_score_adj is the knob on top of it, from -1000 to 1000, added to the score before the choice is made; -1000 makes the score always 0, so that task is never picked. Kubernetes writes that file from the pod’s QoS class, which is the one place QoS decides who dies, and the node-eviction post has the table.
The confusion has a history, which made me feel a little better. The same man page notes that before Linux 2.6.36 the OOM score did factor in the nice value, along with runtime and CPU use. That changed in 2010. It has been a pure CPU knob for a long time.
A quota is a ceiling, nice is a weight
My next question was a sharper version of the same confusion. If a container’s cgroup already says it gets half a core, what is nice even doing? The cgroup decided how much CPU the thing gets.
cpu.max holding 50000 100000 means 50,000 microseconds of CPU time in every 100,000 microsecond period: half a core, and once the 50 ms is spent the group’s threads stop until the next period starts. That is a cap on consumption, and the millicores post walks through how a Kubernetes limit becomes exactly that file. nice has no opinion about the cap. A process at nice -20 in a group that has exhausted its quota is throttled with everything else in the group, and nothing about its nice value refills the bucket.
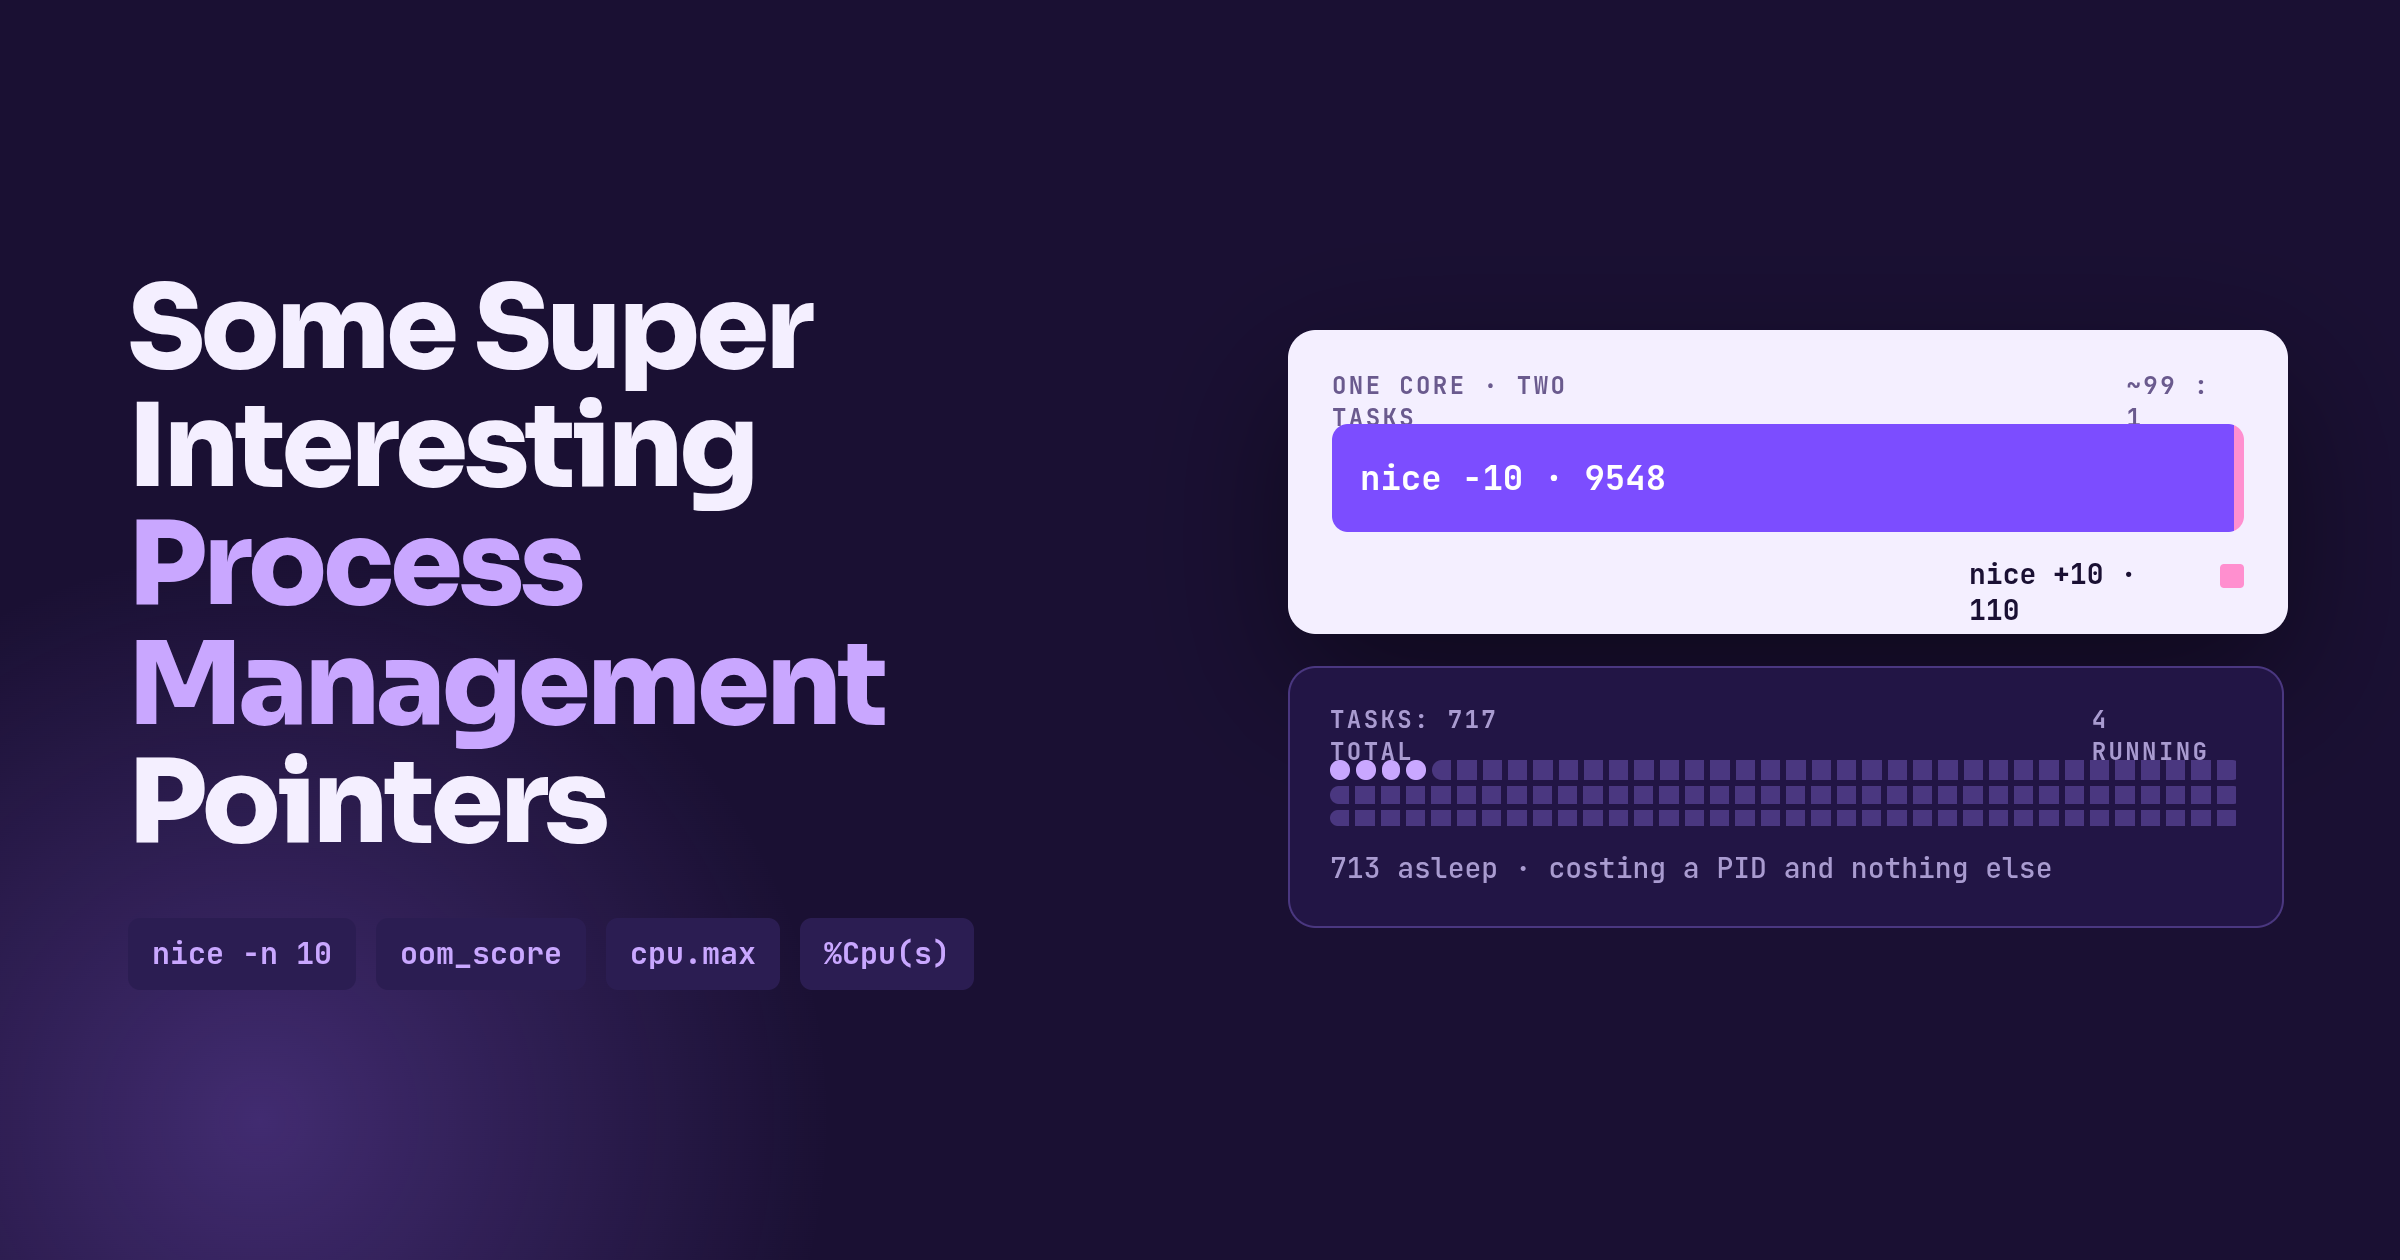
What nice decides is the share a runnable task gets when it is competing with other runnable tasks, and it decides it through weight. kernel/sched/core.c has the table, sched_prio_to_weight, with a comment saying nice levels are multiplicative and each step changes a task’s CPU share by about 10%, implemented as a factor of 1.25 per level. Nice 0 is weight 1024. Nice -10 is 9548. Nice +10 is 110. So the gap between -10 and +10 is not twenty steps on a line; it is a ratio of about 87 to 1, and two CPU-bound tasks at those values split a core roughly 99 to 1.
The interview version of the question goes: process A has a 500m quota and nice -10, process B has a 500m quota and nice +10, both CPU-bound on one core. Which is scheduled more favourably, and can either exceed its quota? Lower nice wins, and no. But the setup hides a catch that sched(7) states plainly: under group scheduling, a thread’s nice value affects scheduling decisions only relative to other threads in the same task group. Two containers are two cgroups. What splits a busy CPU between cgroups is cpu.weight, the thing a Kubernetes CPU request turns into. nice inside container A says nothing to container B; it only reorders A’s own threads among themselves. That is also where it still earns its keep: a service that renices its own background work, a compaction or a log flusher, so the request path wins when the group’s share is contended.
So three knobs, three jobs. cpu.max caps the group. cpu.weight divides a contended CPU between groups. nice divides a group’s share between its own tasks. None of them lets anything past the first.
The %Cpu(s) line is every CPU added up
This is the header from my machine, 32 GB and a day and a half of uptime:
top - 16:34:37 up 1 day, 11:43,  1 user,  load average: 2.00, 1.20, 0.84
Tasks: 717 total,   4 running, 713 sleeping,   0 stopped,   0 zombie
%Cpu(s):  2.7 us,  1.3 sy,  0.0 ni, 95.8 id,  0.1 wa,  0.0 hi,  0.0 si,  0.0 st
MiB Mem :  31781.7 total,   3882.7 free,  11868.5 used,  16030.5 buff/cache
MiB Swap:   2048.0 total,   2046.7 free,      1.2 used.  17273.4 avail Mem
I wanted to know whether the %Cpu(s) line was one core or all of them. It is all of them. The summary is the aggregate over every logical CPU, so 95.8 idle means the machine as a whole is 95.8% idle, and a single thread pinning one core shows up here as one CPU’s share of the total, not as a core at 100. Press 1 inside top and the line splits into %Cpu0, %Cpu1 and so on, one per logical CPU. lscpu or nproc tells you how many lines to expect.
The eight fields, as top(1) defines them:
| Field | Meaning |
|---|---|
us |
time running un-niced user processes |
sy |
time running kernel processes |
ni |
time running niced user processes |
id |
time spent in the kernel idle handler |
wa |
time waiting for I/O completion |
hi |
time spent servicing hardware interrupts |
si |
time spent servicing software interrupts |
st |
time stolen from this VM by the hypervisor |
Two of them deserve a second look. ni is user time from processes running at a positive nice value, carved out of us, so after you renice a batch job its CPU moves from one column to the other; it is 0.0 here because nothing niced was running. st is always 0 on bare metal and the first thing to check on a VM that feels slow: it is time the guest wanted to run and the hypervisor gave to someone else, which does not show in us or sy at all.
717 tasks, 4 running, so what are the other 713 doing?
That second line is where I was left. Tasks: 717 total, 4 running, 713 sleeping. Does 717 mean 717 processes are fighting for the CPU?
No. Four were in state R, and top(1) says even those “should be more properly thought of as ready to run”: R means on a CPU or in the run queue waiting for one. The other 713 are what top calls sleeping, and that is top’s word rather than the kernel’s. procps folds S, D and the I of idle kernel threads into that one number, so ps -eo stat= | cut -c1 | sort | uniq -c is how you see the real split. Most of the S tasks are blocked in a syscall waiting for a socket, a timer, a child, a keypress; the I ones are kworkers with nothing to do. Either way they cost memory and a PID and nothing else. A machine with 717 tasks and a CPU that is 95.8% idle is not a contradiction; it is the normal case. Almost everything is asleep almost all of the time, and the scheduler only ever has to think about the handful that is not.
D is the letter hiding inside that 713 that you actually care about. It is uninterruptible sleep, usually a task waiting on disk or a hung NFS mount, and it usually cannot be killed until whatever it is waiting on comes back. Z gets its own column: a zombie has exited and is waiting for its parent to wait(2) on it, which the pod post covers as PID 1’s other job. The load average counts R and D together. proc(5) describes /proc/loadavg as the number of jobs in the run queue (state R) or waiting for disk I/O (state D), averaged over 1, 5 and 15 minutes. That is why load can climb on a box whose CPUs are idle: twelve processes stuck in D behind a slow disk push the one-minute load towards 12 while %Cpu(s) shows nothing but id and a little wa, and top still files all twelve under sleeping. The 2.00 up top is the same arithmetic over the last minute, against 4 in R at the instant the screen was drawn.
Ending notes
Every one of these was a knob doing less than I assumed. If this is interview prep for you too, the sentence that covers most of it is: nice is a CPU scheduling weight within a cgroup, nothing more. Everything above is the detail behind it.
Three commands make it checkable on your own box. cat /proc/$$/oom_score and cat /proc/$$/oom_score_adj show what the OOM killer would actually read for your shell, and renice does not move either of them. cat /sys/fs/cgroup/cpu.max from inside a container shows the cap that nice cannot lift. And the ps -eo stat= line above tells you how many of your own tasks are asleep right now.
Thanks for your time :)