I have written cpu: 250m into more Deployments than I can count, and until recently I could not have told you what it meant. Everyone says it is a quarter of a CPU. The docs talk about CPU time. A quarter of a CPU’s time over what? A day? A second? Nobody writes down the denominator, so the number stays a thing you copy from the last manifest. This post is the explanation I wish I had read first: where the denominator is, and what the kubelet turns the number into.
You cannot split a core, only its time
A CPU core runs one thread at any instant. Your laptop looks like it is running three hundred things at once because the kernel switches between them every few milliseconds, which is fast enough that nothing seems to stop. So there is no such thing as giving a process half a core. The silicon does not divide. What divides is the core’s time: how many of its milliseconds each thread gets before the kernel moves on to the next one.
One cashier at a shop is the simplest picture of it. You cannot hand a customer half a cashier. You can give them half of the cashier’s minutes.
The unit is CPU-seconds per second
The confusing word is “time”, because the unit is actually a rate, like km/h. One Kubernetes CPU is one second of CPU time for every second of wall-clock time. That is the missing denominator: it is always per second, and it is always a fraction of one core’s seconds.
| Value | Per 1 s of wall-clock time |
|---|---|
1 (1000m) |
1000 ms of CPU time, a whole core |
500m |
500 ms of CPU time |
250m |
250 ms of CPU time |
1m |
1 ms of CPU time |
2 (2000m) |
2000 ms of CPU time, which needs two cores running in parallel |
So one millicore is one millisecond of CPU work per second. The docs add that 0.1 and 100m are the same value, that nothing finer than 1m is allowed, and that the amount is absolute, so the same 500m asks for the same thing on a 2-core node and a 64-core node.
The last row is why it has to be time and not a core. You cannot fit two seconds of work into one second on one core, but two cores can do it between them. CPU time adds up across cores, and the kernel is free to add it up on whichever cores it likes.
What a limit turns into
The kernel does not check once a second. It checks in a smaller window called the CFS period, which the CFS bandwidth control docs default to 100 ms. The kubelet uses the same number: in pkg/kubelet/cm/helpers_linux.go the period is a constant, QuotaPeriod = 100000 microseconds, and the quota is milliCPU * period / 1000. It can be changed with cpuCFSQuotaPeriod behind the CustomCPUCFSQuotaPeriod feature gate, and almost nobody does.
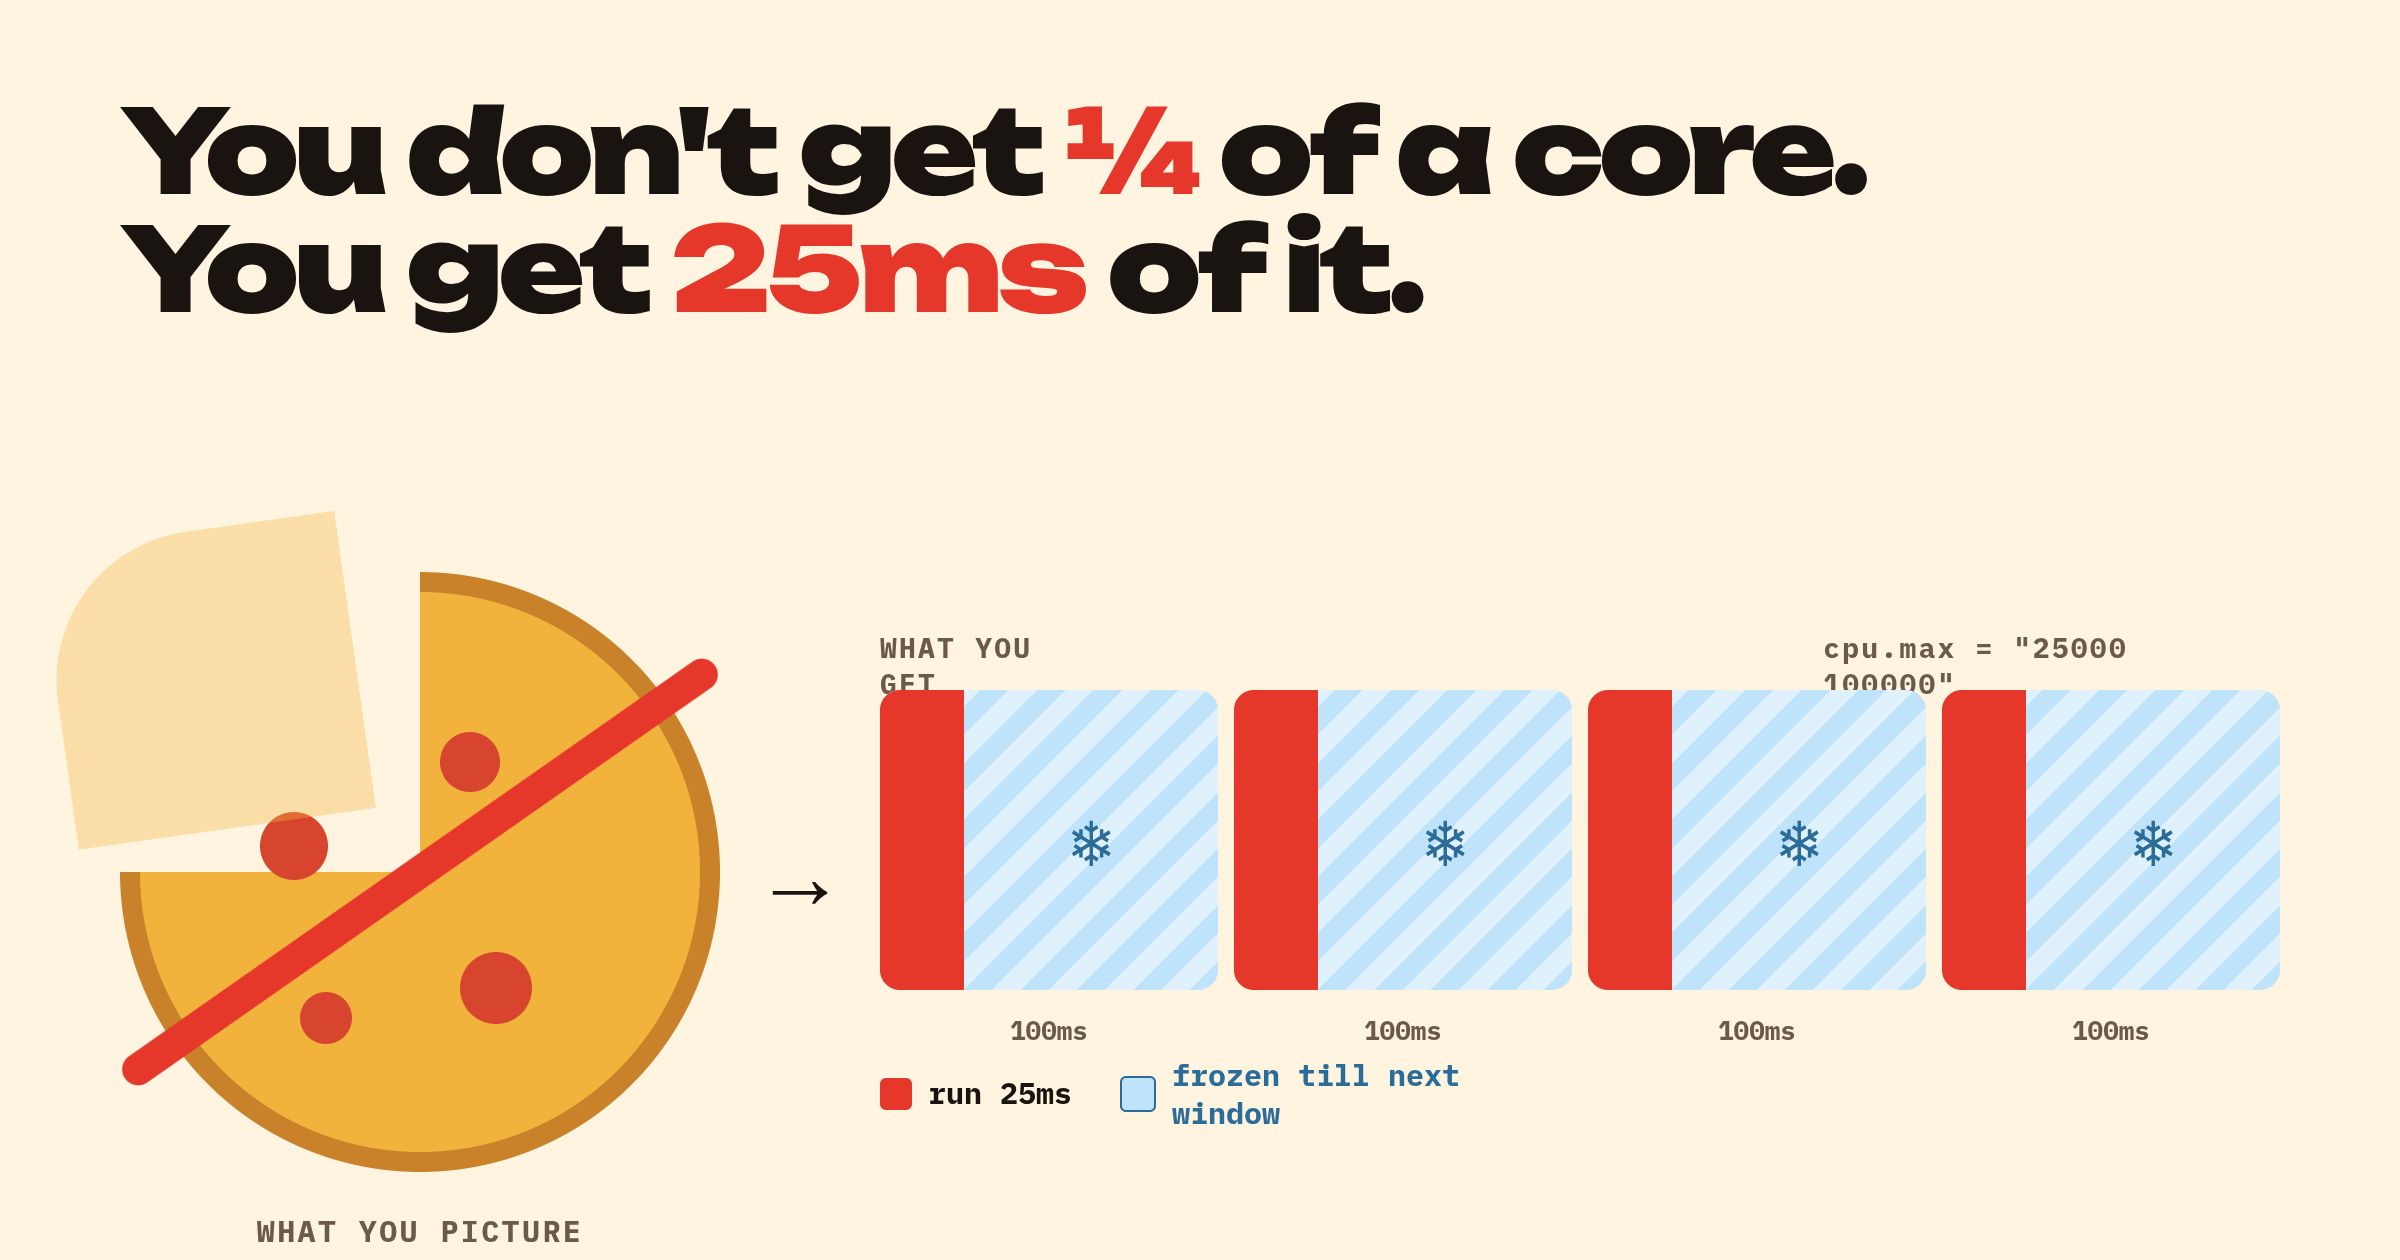
So limits.cpu: 250m becomes 250 * 100000 / 1000 = 25000, and on a cgroup v2 node you can read it back from inside the container:
$ kubectl exec -it api-7d4c9-x2k1p -- cat /sys/fs/cgroup/cpu.max
25000 100000
Quota first, period second, both in microseconds. On cgroup v1 the same two numbers are cpu.cfs_quota_us and cpu.cfs_period_us. A container with no limit gets the kernel default of max 100000: the same period, nothing to run out of.
The mechanism is a bucket. At the start of each 100 ms period the container gets 25 ms of CPU time. Its threads spend from that bucket as they run, and when it is empty they stop, all of them, until the next period starts and the bucket is refilled. The kernel docs say it plainly: throttled threads will not be able to run again until the next period when the quota is replenished. That is what a CPU limit is. Not a slower CPU, a CPU that is switched off for the rest of the window once you have used your share of it.
“On any cores” is the part that bites
The 25 ms is not tied to a core. It can be spent as 25 ms on core 3, or 10 ms on core 0 and 15 ms on core 7, or four threads on four cores each running about 6.25 ms. The kernel hands quota out to each CPU’s run queue in 5 ms slices (kernel.sched_cfs_bandwidth_slice_us), so the real picture is lumpier than that, but the total is still 25 ms per period however it is split.
That last case is the production gotcha. A Go service, a JVM with its thread pools, a Node app with workers: four busy threads burn through a 25 ms bucket in about 6.25 ms of wall time, and then the whole container is frozen for the remaining 93.75 ms. Averaged over a second it used a quarter of a core, exactly what the limit said. The CPU graph looks calm. Meanwhile every request that arrived during the freeze waited up to 94 ms for nothing, and p99 latency is terrible.
The counter that shows this is container_cpu_cfs_throttled_periods_total from cAdvisor, the number of periods in which the container was throttled, next to container_cpu_cfs_periods_total for the total. The same two numbers are nr_throttled and nr_periods in the container’s cpu.stat. High ratio, low CPU graph: this is why. Whether you should set CPU limits at all is an argument for another post; this one is only about what a limit does when you set it.
A request is a weight, not a cap
requests.cpu: 250m never throttles anything. It does two unrelated jobs.
The first is placement. The scheduler only puts the pod on a node where the sum of requests, including this one, fits inside the node’s allocatable CPU. That is accounting on paper.
The second is a share of the node when the node is busy. The kubelet turns the request into cgroup v1 shares at 1024 per CPU, so 250m is 256 shares. Cgroup v2 has no shares, only cpu.weight in the range 1 to 10000, so the shares get converted, and the number you see depends on who did the converting. The kubelet writes the pod’s cgroup with the linear formula from KEP-2254, 1 + (shares - 2) * 9999 / 262142, which makes 250m a weight of 10. The container cgroup inside it is written by the OCI runtime, and runc 1.3.2 and crun 1.23 switched to a log-quadratic curve that puts 1024 shares back at the cgroup default of 100 instead of 39. On a node with one of those runtimes, 250m inside the container should read as 35; on an older runc it is 10, the same as the pod:
$ kubectl exec -it api-7d4c9-x2k1p -- cat /sys/fs/cgroup/cpu.weight
35
The absolute number is not the point, and since the new curve maps several millicore values onto one weight you cannot reliably read it backwards anyway. What the kernel uses is the ratio.
Weights only matter under contention. The cgroup v2 docs describe the controller as work-conserving: only children that can use the resource right now take part in the split. On an idle node a pod with a 250m request and no limit can use the whole machine. When two pods want the same core, the kernel divides its time in proportion to their weights.
Pod A requests 250m and pod B requests 750m, both busy and both fighting over the same core. Their pod cgroups carry weights of 10 and 30, so A gets about a quarter of the core and B about three quarters. B goes idle, A gets the whole core.
Time on what, exactly?
The other phrase I could not parse was “one vCPU or hyperthread’s worth of time”, which raises the question of what Kubernetes counts as a CPU. The answer is a logical CPU, the smallest thing Linux can schedule a thread onto, and that is usually not a physical core.
A physical core is the silicon that executes instructions. With simultaneous multithreading, Intel’s Hyper-Threading or AMD’s SMT, one core presents itself to Linux as two CPUs. The core keeps two threads loaded and switches to the other whenever the first stalls, on a memory load say, so its execution units sit idle less often. A machine with 8 physical cores and SMT on shows 16 in nproc, and Linux schedules on all 16 as if they were separate.
The catch is that the two siblings share one core. If both are flat out you do not get twice the work. The usual rough figure is something like 1.2 to 1.3 times a single thread, it depends heavily on the workload, and I have not measured it myself. Each hyperthread is a weaker thing than a whole core.
A vCPU is the cloud word for a CPU your VM can see, and on most providers it is one hyperthread. Compute Engine’s docs say it directly: each hardware thread is called a virtual CPU. AWS says the same on its CPU options page, each thread is a vCPU, with an m5.xlarge being two cores at two threads each, and Hetzner’s FAQ puts one dedicated vCPU at one thread of a physical core. So a 4-vCPU VM is about two physical cores of silicon. The exception is Arm: AWS’s spec tables list one thread per core for Graviton instances, and GCP says the same for its Arm machine types, so there 1 vCPU is 1 physical core.
Kubernetes does not know or care about any of that. It counts whatever Linux reports as a CPU. One Kubernetes CPU is one second per second on one logical CPU, which on an x86 cloud VM means one hyperthread. Two things follow.
“1 CPU” is not a fixed amount of work. 1000m on a 3.5 GHz EPYC does more than 1000m on a 2.2 GHz Xeon, and 1000m on a hyperthread whose sibling is busy does less than 1000m on one whose sibling is idle. Kubernetes measures time, and time is all it measures.
Node capacity is in logical CPUs too. An 8-vCPU VM on a dedicated Hetzner plan shows capacity.cpu: 8, which is 8000m of schedulable time backed by roughly four physical cores. The two numbers that Kubernetes and Linux agree on are these:
$ kubectl get node worker-1 -o jsonpath='{.status.capacity.cpu}'
8
$ ssh worker-1 nproc
8
Nothing in that output says four cores. The 2:1 comes from the provider’s spec sheet, and inside a VM even lscpu only shows whatever topology the hypervisor chose to present.
Ending notes
250m means: in every 100 ms, you may run for 25 ms in total, on any cores. The request decides your share of the node when it is crowded. The limit decides when you get frozen. They are set by two different kernel mechanisms, a weight and a quota, and neither of them is a piece of hardware with your name on it.
The two cat commands above are the quickest way to make it real. Open a shell in a pod that has a request and a limit, read cpu.max and cpu.weight, and check them against the millicores in the manifest.
Thanks for your time :)